Testing Isn't Dead. The Test Phase Is.
TL;DR
Testing isn't dying. The test phase is. "Ship it and fix it fast" is a real bet for small repos — and it only holds when bugs announce themselves and damage is reversible. Agents that write the code cannot be the examiner of that code. Past a single deployable, the question is whether you find out before the user does, and whether you can take it back if you don't.
The argument goes like this.
Coding agents write better code than they did a year ago. Bug density is falling. When something does break, a monitoring agent flags it, another agent reads the trace, writes the fix, opens the PR, and ships. Minutes, not sprints.
So why pay for a test suite? Why staff QA? Why maintain a regression pack that takes two hours to run and breaks every time someone renames a div?
For a lot of small teams, this isn't a hypothetical. It's already how they ship. And I don't think they're being reckless.
I think they're running a specific bet, and the bet only holds under specific conditions.
The bet nobody states out loudDirect link to The bet nobody states out loud
"Ship it and fix it fast" rests on two assumptions:
1. The bug will announce itself.
2. The damage is reversible.
That's it. That's the whole model.
When both hold, skipping pre-merge testing is rational. A 500 error spikes in your dashboard, an agent catches it, the fix is live before most users refresh. Pre-merge testing would have cost you more than the outage did.
Now break either assumption.
A pricing rule applies the wrong discount tier. No exception. No error rate. No alert. The system is behaving exactly as written, and what's written is wrong. Nothing announces itself. You find out at month-end close, or when a customer does the math.
Or: a migration drops a column. A batch job emails 40,000 people. A permissions check inverts and the wrong tenant sees the wrong data. Mean time to recovery is now irrelevant. You can revert the code. You cannot revert the consequence.
So the real question isn't "is testing dead." It's:
how much of your failure surface is silent, and how much of it is irreversible?
That ratio is what decides how much testing you need. Not company size, not repo size. Those are just proxies.
The part agents structurally can't doDirect link to The part agents structurally can't do
Here's the argument I find hardest to counter, and it isn't about capability. It's about position.
An agent that writes code, then writes tests for that code, is generating both from the same understanding of the problem. If that understanding is wrong, the tests encode the wrong behavior as correct and pass cleanly.
The author cannot be the examiner.
This isn't a limitation that gets solved by a better model. A more capable agent with a misread requirement writes a more thorough test suite around the wrong behavior. Self-generated tests find inconsistency between code and intent-as-the-agent-understood-it. They can't find wrongness, because wrongness is defined outside the system that produced the code.
This is the oracle problem, and software testing has had it since long before LLMs. Agents didn't create it. They just made it the main event, because now the code and the tests come from the same place.
Someone or something independent of the implementation has to hold the definition of correct. That role doesn't disappear when code generation gets cheap. It gets more load-bearing.
Why small repos hide the problemDirect link to Why small repos hide the problem
I'd guess most teams shipping this way today have a single deployable, a handful of integrations, and a codebase an agent can hold in context. I can't verify that as a distribution, but it matches what I see.
Under those conditions the agent has near-total visibility. The failure modes are local. The blast radius is one service. Detect-and-fix genuinely works.
Then you grow.
Four services become twelve. A queue shows up. A third-party payment provider shows up, then a second one for a different geography. Some flows are async now. Some state lives in a partner's system you can't inspect.
What changes isn't the number of bugs. It's the kind. Failures stop being "this function is wrong" and start being "service A and service C disagree about what a cancelled order means, and only under retry."
No single PR diff contains that bug. It isn't in the diff. It's in the gap between two diffs written months apart by different agents in different repos, neither of which was wrong on its own.
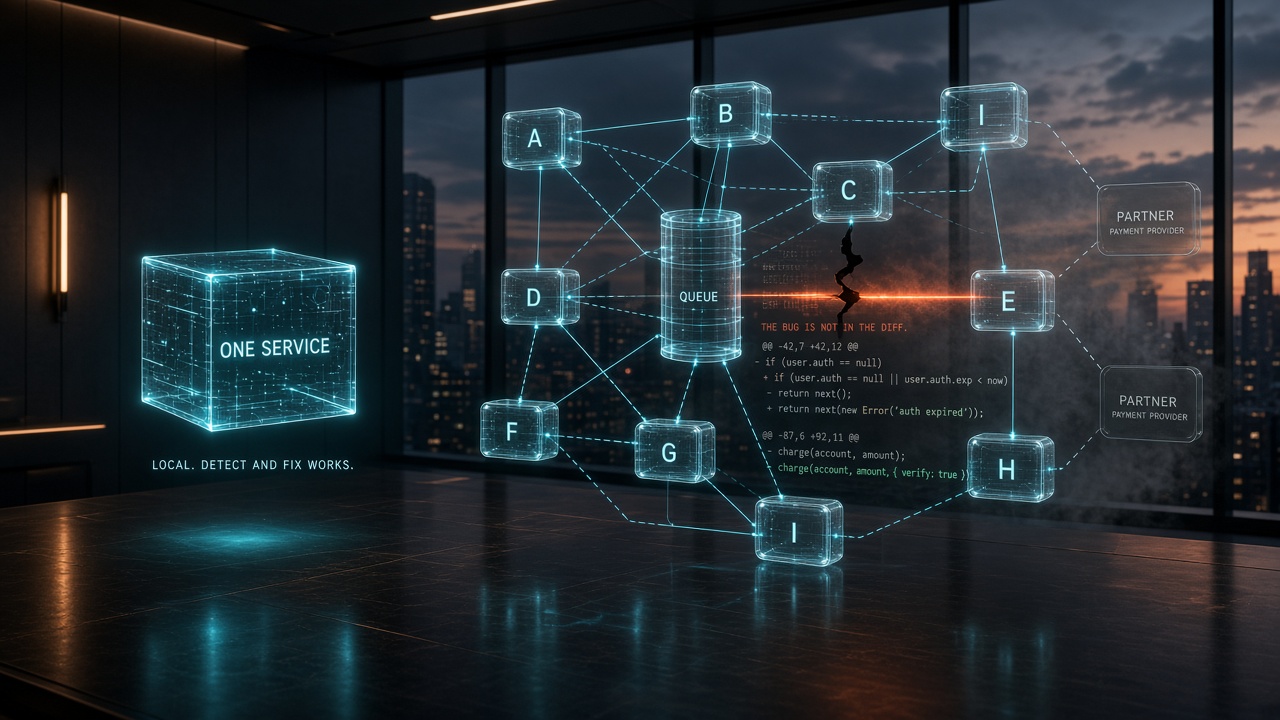
This is where I think the detect-and-fix loop quietly degrades, and it degrades before anyone notices, because the loop still works on everything it can see.
Enterprise was never running this betDirect link to Enterprise was never running this bet
At enterprise scale the numbers point the other way and always have.
The failure surface is enormous. The irreversible fraction is large: money moves, regulated records get written, contractual SLAs attach to uptime. A rollback isn't a git revert, it's a coordination problem across teams and change windows.
And the cost asymmetry is brutal. A test suite costs a known, boring amount every month. A single silent defect in a payment or compliance path can cost multiples of the annual QA budget in one incident. I'm not putting a number on that because any number I gave you would be invented. The asymmetry is the point, not the magnitude.
Nobody in that environment is going to trade a known cost for an unbounded one because the turnaround time on fixes got better.
So what actually diesDirect link to So what actually dies
Something is dying. It's just not testing.
Dying: hand-writing Selenium and Playwright scripts as a full-time craft. Manual regression passes as a recurring headcount line. Test case authoring measured by volume. Suites so brittle that maintaining them costs more than the bugs they catch. That work was always overhead, and it should go.
Not dying: deciding what must never break. Defining correct when the spec is ambiguous. Test data and environments. Verifying integrations you don't control. Performance, security, accessibility. Confirming behavior in production, not just in CI.
None of that is "writing tests." All of it is testing.
Regression testing gets more importantDirect link to regression-testing-gets-more-important
This is the one I'd push back on hardest.
Agents raise change velocity. More code changes per day, across more of the repo, by contributors with no memory of why a weird conditional exists. Regression surface scales with change rate.
The case against regression testing was never that regressions stopped happening. It was that the suite was slow, flaky, and expensive to maintain. Those are real complaints about a specific implementation of regression testing, not about the need for it.
Fix the flakiness and the maintenance cost and the objection evaporates. Skip it and you're relying on production to tell you what broke, which brings you right back to the two assumptions: silent and irreversible.
Where QA goesDirect link to Where QA goes
Away from producing tests. Toward owning the answer to "what breaks us."
Classifying flows by blast radius. Reviewing agent-generated tests specifically for the failure mode agents can't self-catch — an assertion that's wrong rather than missing. Designing the evidence a release needs before it ships. Owning the independent verification layer, whoever or whatever staffs it.
That last part is the load-bearing one. A dedicated testing agent did not write the patch. It reads the diff cold, maps which journeys are in the blast radius, and runs them in a real browser. The point isn't the brand. The point is the separation: the definition of correct has to sit outside the loop that produced the code.
Fewer people doing that than there were doing manual regression. I'd expect the role to consolidate and move up the stack. That's a guess about how this plays out, not a forecast I can support with data, and anyone selling you a confident prediction here is selling you something.
The short versionDirect link to The short version
Testing isn't dying. It's losing its slot in the calendar.
It stops being a phase between "done" and "shipped" and becomes continuous evidence produced alongside the code, by something independent of whatever wrote the code.
For a small team on a small repo, detect-and-fix is that evidence, and it's enough. That's a real answer, not a compromise.
For everyone past that point, the question isn't whether you need testing. It's whether you find out before the user does, and whether you can take it back if you don't.
No. What is dying is the test phase — a calendar slot between "done" and "shipped," plus the craft of hand-writing brittle Selenium and Playwright scripts. Deciding what must never break, holding an independent definition of correct, and verifying silent or irreversible failure modes still have to happen. They just stop living in a phase.